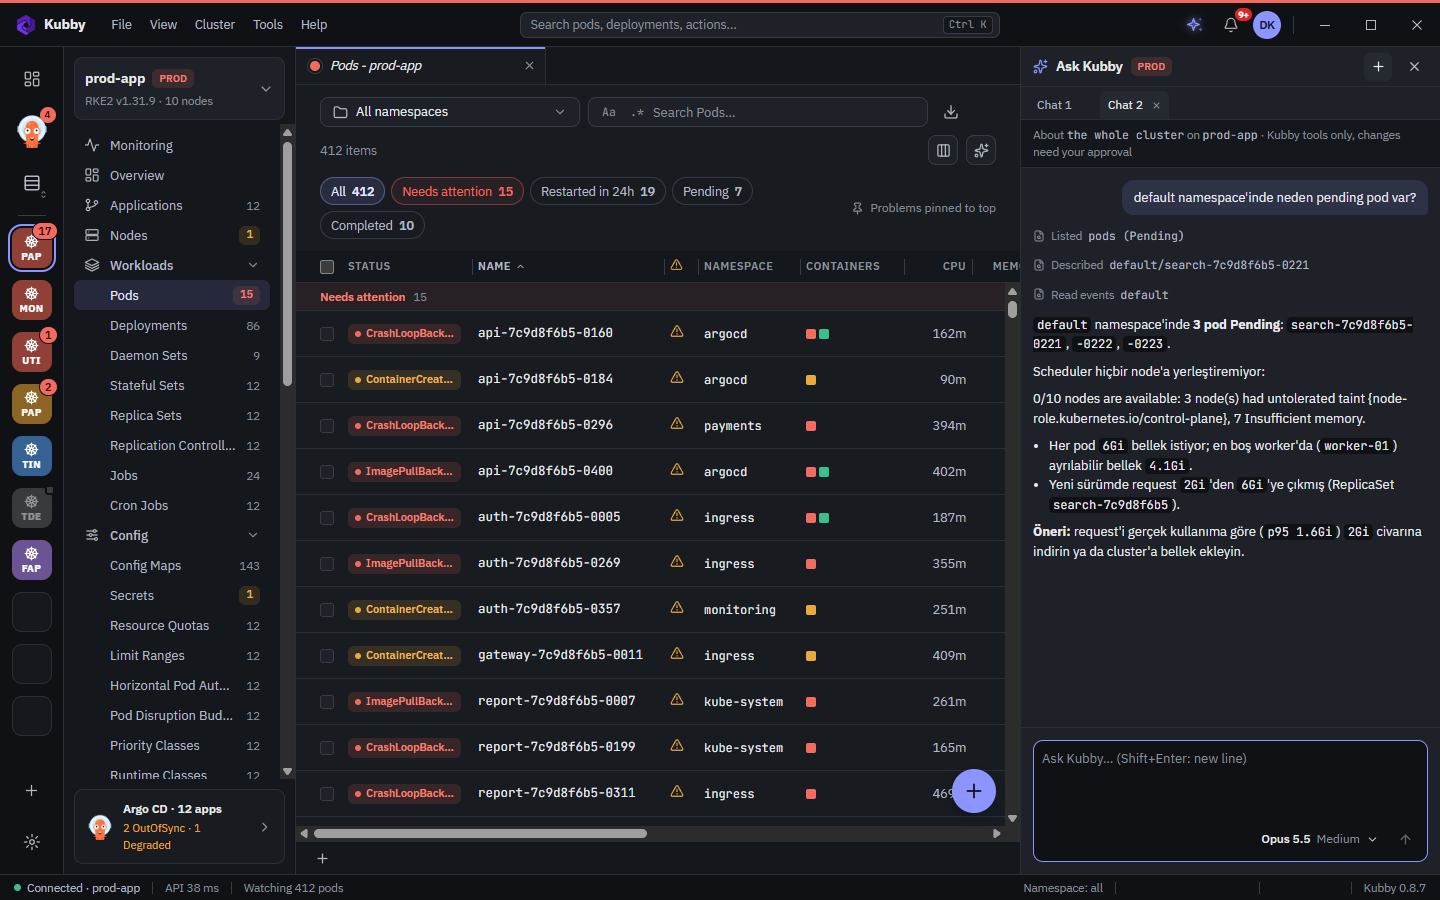
Pending pods: when the scheduler cannot place a pod
A pod stays Pending when the scheduler finds no node that fits it, or when something it needs (a volume, an image pull, a quota) is not ready. The scheduler writes the exact reason into the pod's events.
Read the scheduler's message
kubectl describe pod <pod> -n <ns>and look for aFailedSchedulingevent, for example:0/10 nodes are available: 3 node(s) had untolerated taint {node-role.kubernetes.io/control-plane}, 7 Insufficient memory.- The message counts nodes per reason. Fix the reason that covers the nodes you expect the pod to use.
Reasons and fixes
| Event says | Meaning | Fix |
|---|---|---|
Insufficient cpu / Insufficient memory | No node has enough unrequested capacity for the pod's requests | Lower requests to real usage, free capacity, or add nodes. Note that requests count, not usage. |
untolerated taint | Nodes are tainted (control plane, GPU, dedicated pools) | Add a matching toleration, or run the pod elsewhere on purpose. |
didn't match Pod's node affinity/selector | nodeSelector or affinity matches no node | Fix the labels on nodes or in the selector. |
pod has unbound immediate PersistentVolumeClaims | The PVC is not bound | Check the StorageClass, the provisioner and kubectl describe pvc. |
volume node affinity conflict | The volume lives in a zone where no suitable node is free | Add capacity in that zone or use WaitForFirstConsumer binding. |
Too many pods | Nodes hit their pod limit | Add nodes or raise maxPods. |
exceeded quota (on the ReplicaSet) | A ResourceQuota blocks the pod from being created at all | Raise the quota or lower requests; check kubectl describe quota -n <ns>. |
Capacity is about requests
The scheduler places pods by their requests, not by what nodes really use. A cluster can show 40 % CPU usage and still refuse pods because requests add up to 100 %. Compare requests per node with allocatable before adding hardware.
The Kubby way
Pods the scheduler cannot place appear in "Needs attention" as Unschedulable, with the scheduler's message and a suggestion; pods stuck in Pending for other reasons are flagged too. The Pods list has a Pending filter. With Monitoring, the Capacity tab shows requests per node, overcommit and what is left if the biggest node fails.